Watch
Continually monitors conditions. The agent wakes on a scheduled check-in at an adaptive cadence, or a monitor-triggered alert.

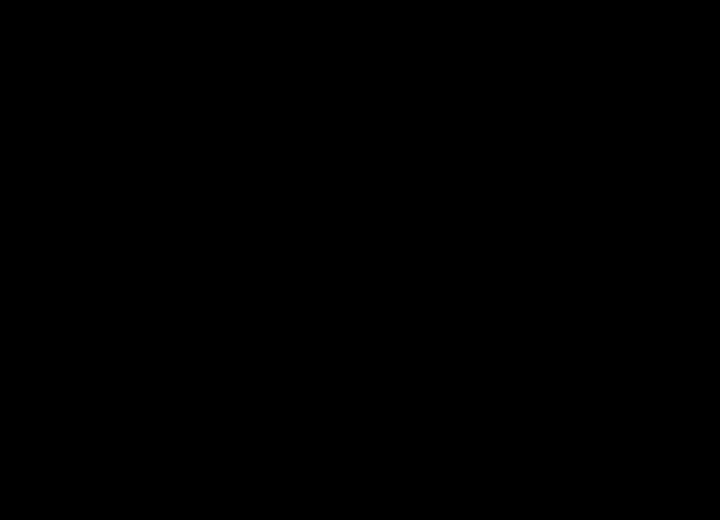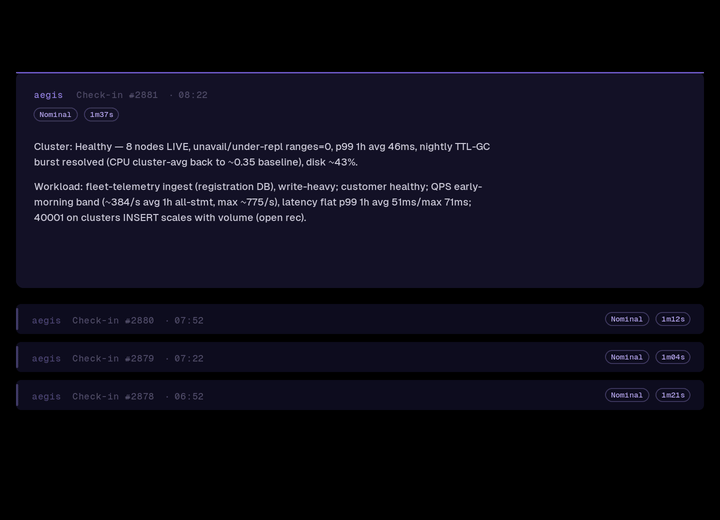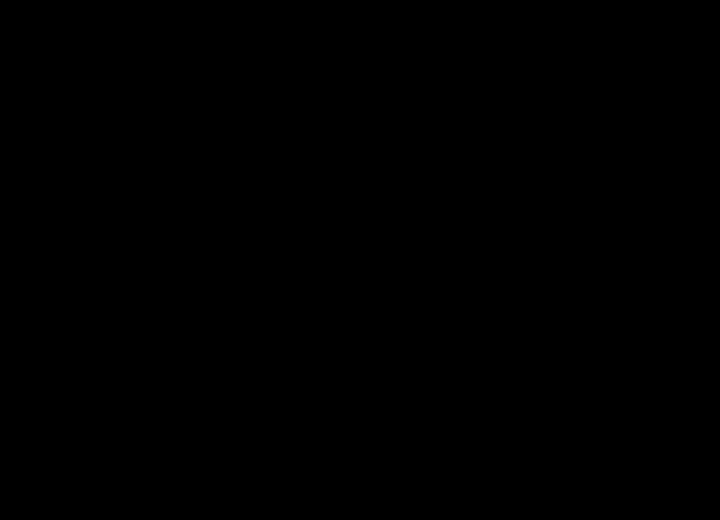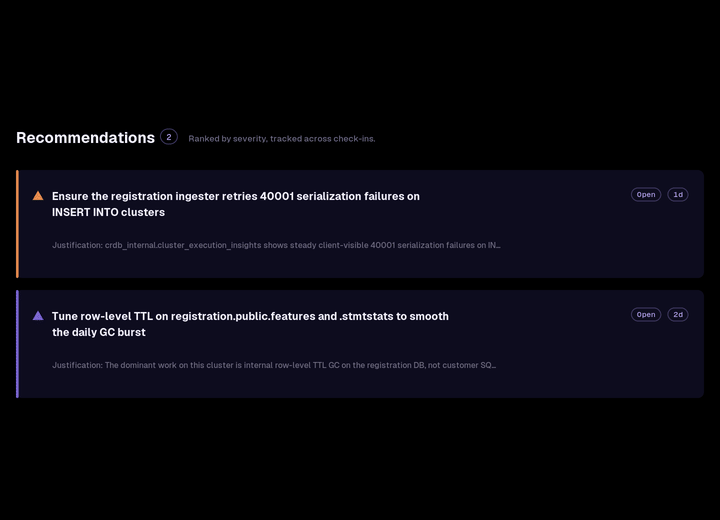
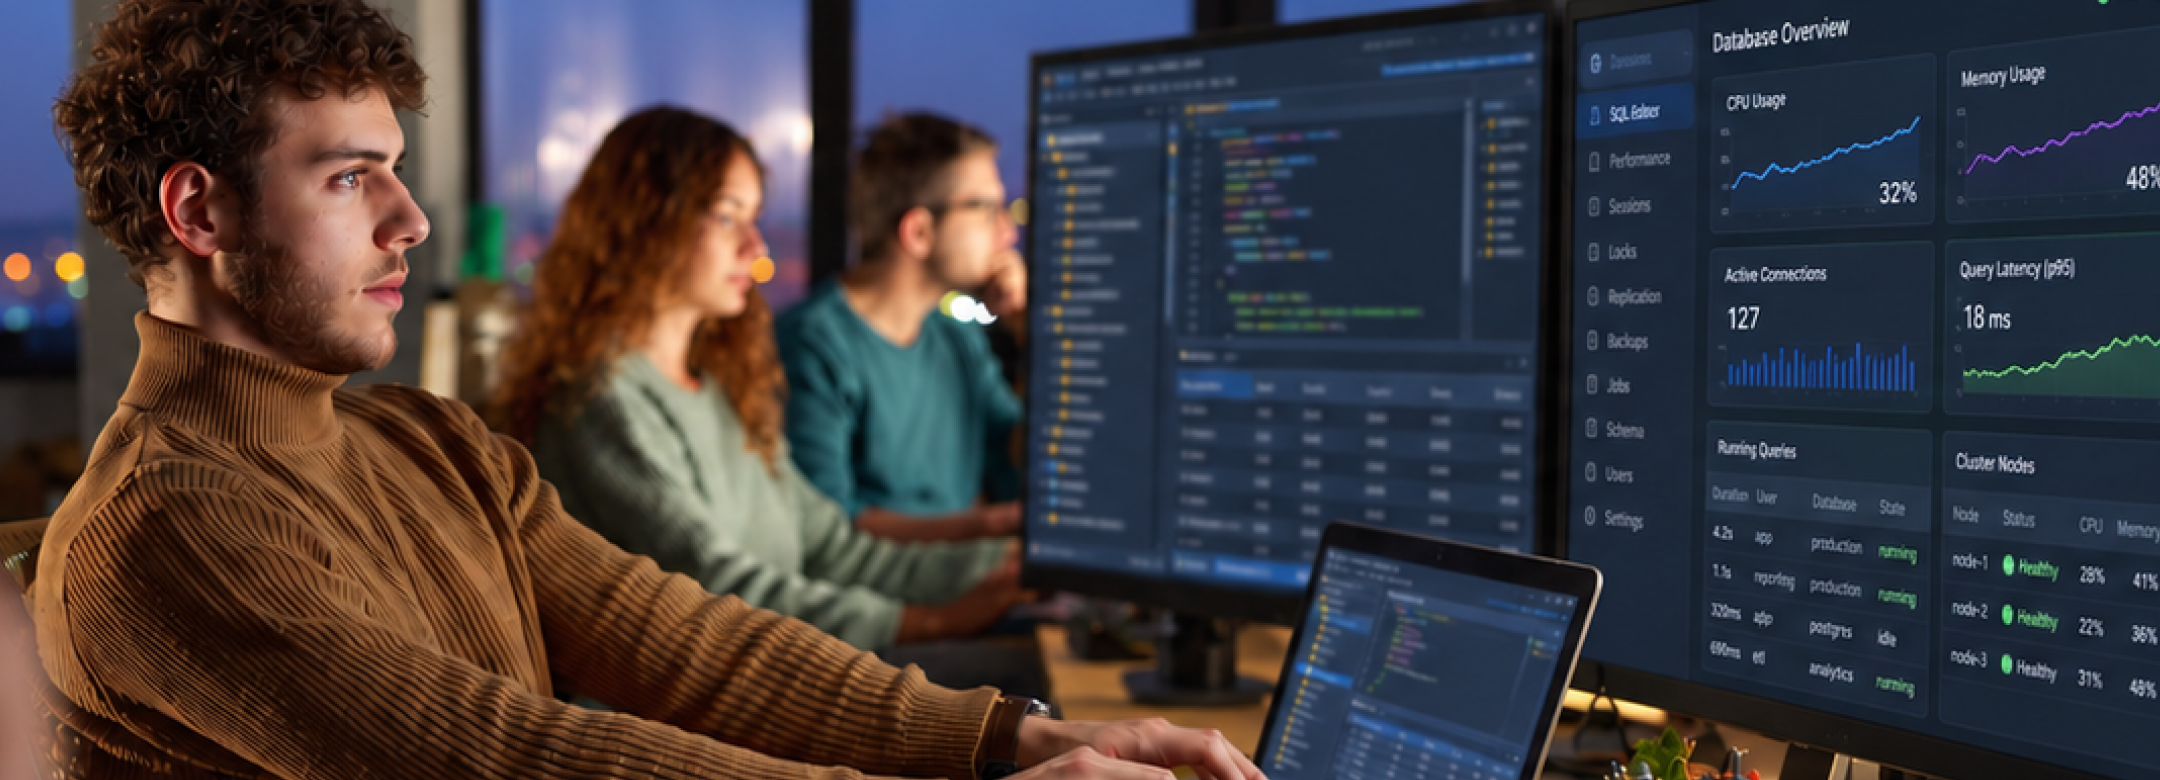
Cluster vitals, workload texture, query behavior. Aegis connects the signals no team can watch alone and turns them into decisions you approve.
Your team can no longer watch everything. Monitoring, incident detection and day-to-day ops fill the week, leaving no room for platform strategy, while agents are shipping faster than anyone can keep up with by hand.
Aegis works like a senior database architect that never sleeps. It can:
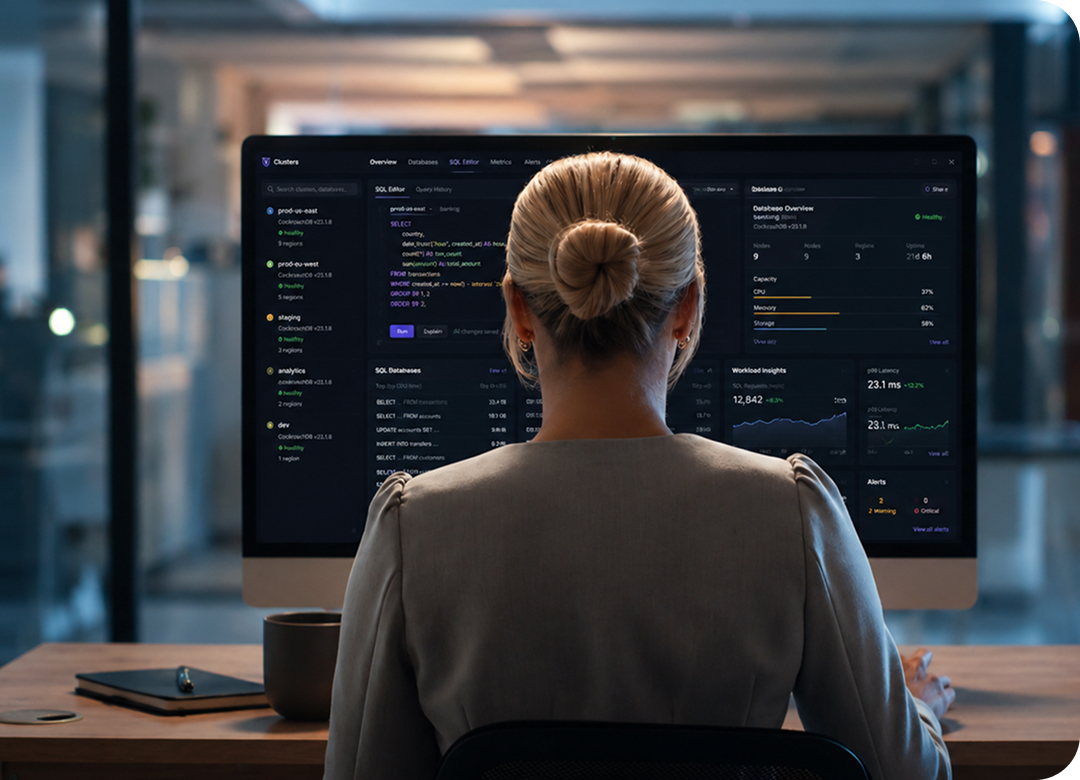
Aegis catches the things that take expertise or time most teams don't have, publishing what it observed, why it diverged, and the exact steps to remedy:
Continually monitors conditions. The agent wakes on a scheduled check-in at an adaptive cadence, or a monitor-triggered alert.
Gathers the current cluster state, topology, and workload signals for a current view.
Spots what diverged from the learned baseline to continuously give up-to-date, high-quality recommendations.
Traces the root cause through the query plan, schema, and cluster configuration.
Produces operator artifacts and actionable remediation steps with full supporting evidence.
Insights on steroids — that was my first reaction. We can be a bit lazy when it comes to fixing unused-index warnings or optimizing schemas unless performance is degrading. But Aegis is proactive at identifying and flagging potential problems before they escalate. On the flip side, Aegis is also reactive and this is where it really clicked for me. During an incident, being able to ask the agent what's going on and have it act like a DBA reading the detailed metrics is so valuable. It will reduce the need to page an SRE or open up a support ticket.
Michael Oakley, Staff Engineer, Primer